Google Genie 4 Adds Audio and Real-Time Edits to Simulated Worlds
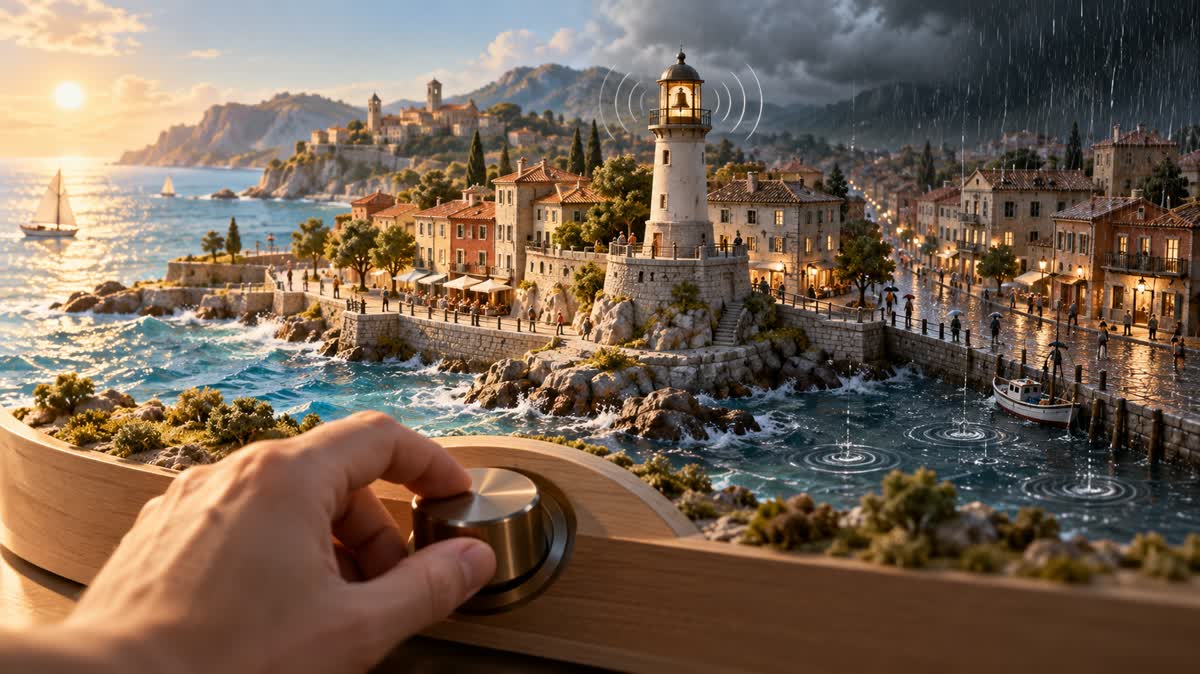
Google DeepMind released Genie 4 in research preview on October 27, adding real-time audio and text-driven scene edits to its interactive world model. Access initially goes to trusted testers, rather than a general public release.
The model generates explorable environments from text and image prompts. Users can navigate with keyboard and mouse, then type instructions while a simulation is running to change weather, adjust the camera or introduce objects and people. Generated sound can include ambient noise, music and dialogue that accompanies the scene.
A simulation partner for Gemini
DeepMind says Genie 4 incorporates capabilities from the Gemini family: Gemini Omni helps anchor simulations in real-world appearance and behavior, while other Gemini models contribute reasoning for continuity.
In an early robotics experiment, Gemini 4 Argon produces a multi-step task plan and passes the steps to Genie as text captions while the simulation renders. That demonstrates a possible planning-and-simulation workflow, not proof that robots can safely execute those plans in the physical world.
Access and remaining limits
Google says access will expand to Google AI Ultra subscribers through Project Genie and to early-access partners of the Gemini API and Google AI Studio. Its model page describes that expansion as coming soon, without a firm launch date.
The limitations remain material: objects and visual details can drift, complex interactions between multiple agents remain difficult, and real-world locations are not reproduced perfectly. Continuous interaction lasts only a few minutes, and audio accuracy is still a research problem.
For developers, the concrete advance is a more steerable audiovisual simulation—not yet a dependable, long-running replacement for a conventional simulator.